Transcript – Audio Transcription App with Speaker Diarization
Type: Software Status: POC Tech Stack: Python, FastAPI, SQLAlchemy (async), Celery 5, Redis 7, PostgreSQL 16, faster-whisper/WhisperX/OpenAI Whisper, PyTorch (CUDA 12.6), React 18, Vite, TypeScript, Docker Problem Statement Transcription of meetings, interviews, and conferences requires not only speech-to-text but also speaker recognition (who said what?). Cloud-based services are expensive and problematic from a data privacy
THE IDEA
Transcript – Audio Transcription App with Speaker Diarization
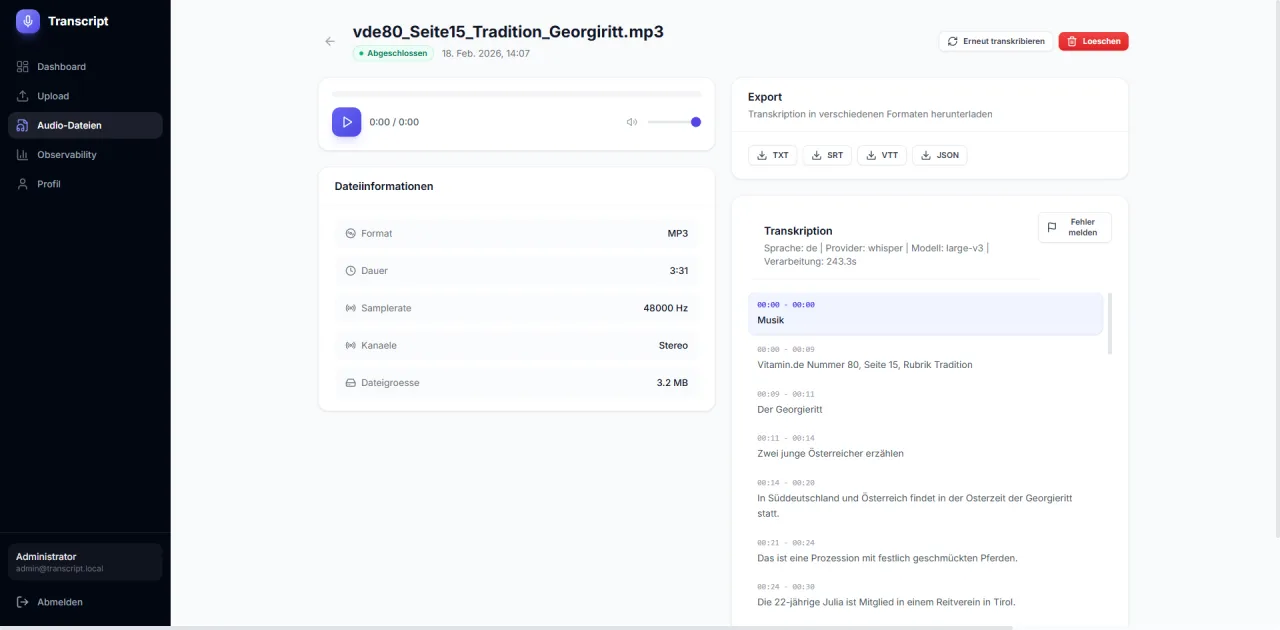
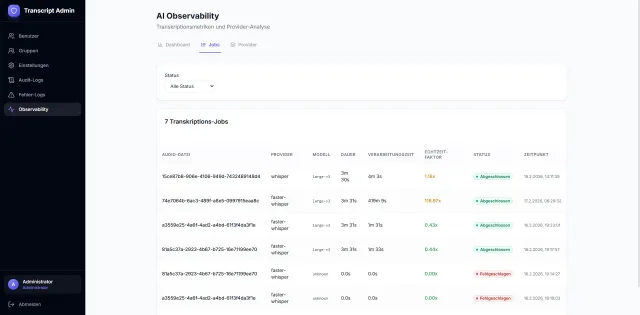
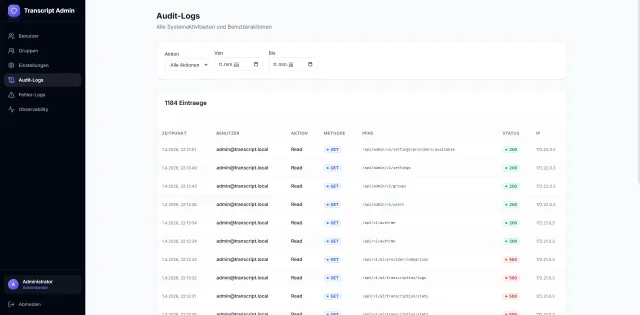
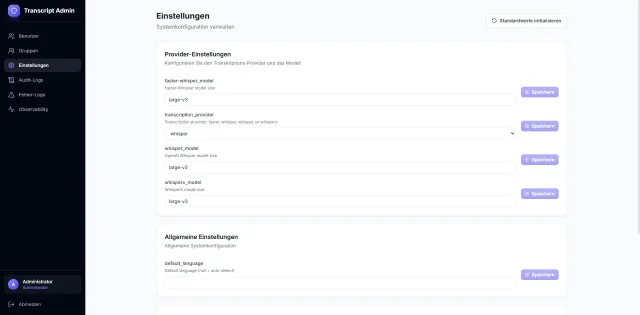
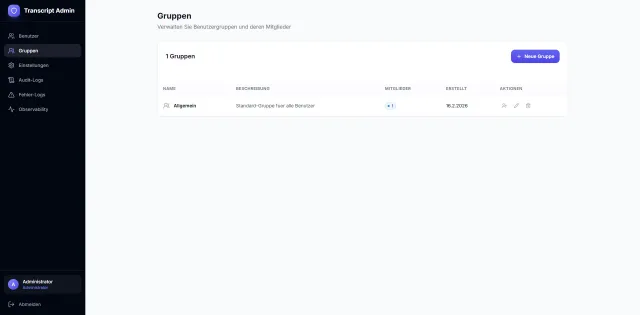
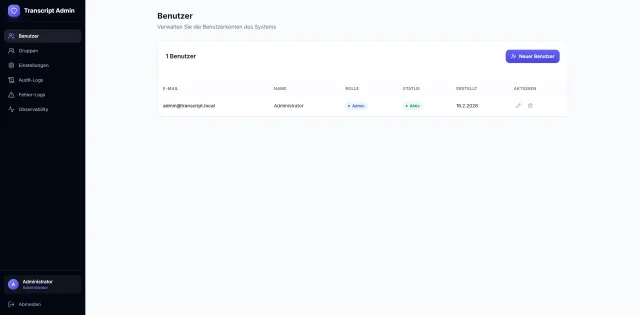
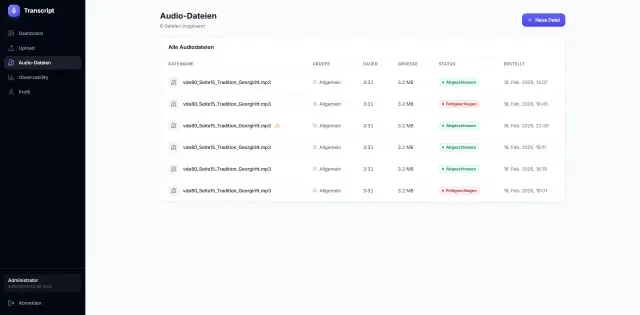
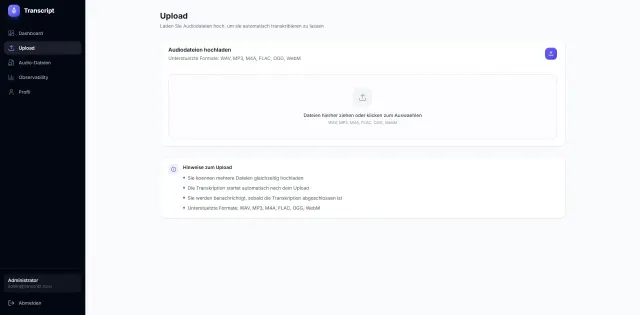
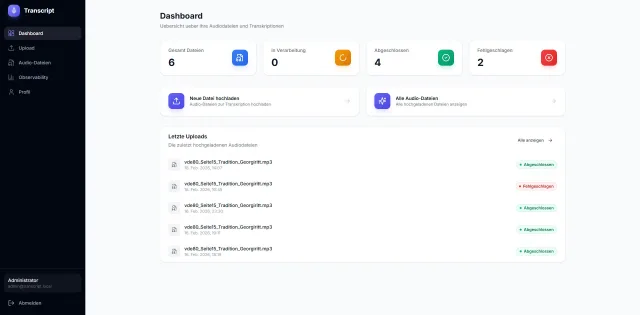
Type: Software Status: POC Tech Stack: Python, FastAPI, SQLAlchemy (async), Celery 5, Redis 7, PostgreSQL 16, faster-whisper/WhisperX/OpenAI Whisper, PyTorch (CUDA 12.6), React 18, Vite, TypeScript, Docker Problem Statement Transcription of meetings, interviews, and conferences requires not only speech-to-text but also speaker recognition (who said what?). Cloud-based services are expensive and problematic from a data privacy perspective (GDPR). Local alternatives rarely offer comparable quality, no provider comparison, and no admin dashboard for monitoring quality and performance of different Whisper variants. Description A complete transcription platform with three Whisper variants (faster-whisper, OpenAI-Whisper, WhisperX), automatic GPU acceleration (CUDA), optional speaker diarization, and provider selection per upload. Offers a user frontend and admin dashboard with observability (provider comparison, job logs, error rates, charts), user/group management, audit logs, and export functions. Use Case Upload audio files and automatically convert them to text — with recognition of who is speaking. Link: https://github.com/rawk7000/transcript (private repo)
Impressions
KEEP EXPLORING
More discoveries
Three more pieces from the archive.
 PROJEKTE
OUTPOST Tactical – Offline AI Field Intelligence
Type: Software Status: Beta Tech Stack: Python, FastAPI, Uvicorn, Ollama (local LLM/vision inference), LanceDB (RAG), SQLite, rasterio/shapely/pyproj, custom PMTiles read...
↗ PROJEKTE
diff_dirs – Recursive Directory Comparison
Type: Software Status: Production Tech Stack: Python 3.8+, PyYAML, difflib, hashlib, HTML/CSS/JavaScript (generated report) Problem Statement Not every project state live...
↗ PROJEKTE
kAI zero Player
Type: Software Status: Beta Tech Stack: Python, python-vlc, pygame (Joystick), tkinter Problem Statement Art installations and exhibitions often need a dedicated, robust...
↗SEND A SIGNAL
LET’S MAKE
SOMETHING
monstrous.
An idea beyond safe waters?
For extraordinary collaborations, consulting and workshops: send a signal.